Benchmarks

This page shows a checked-in benchmark snapshot for the numpy and jax backends.
The artifacts are generated manually so routine docs builds stay fast and deterministic.
The figure includes forward runtime, inverse runtime, a 3-channel JAX batch-vs-serial
comparison, and round-trip reconstruction error against the original real-valued input signal.
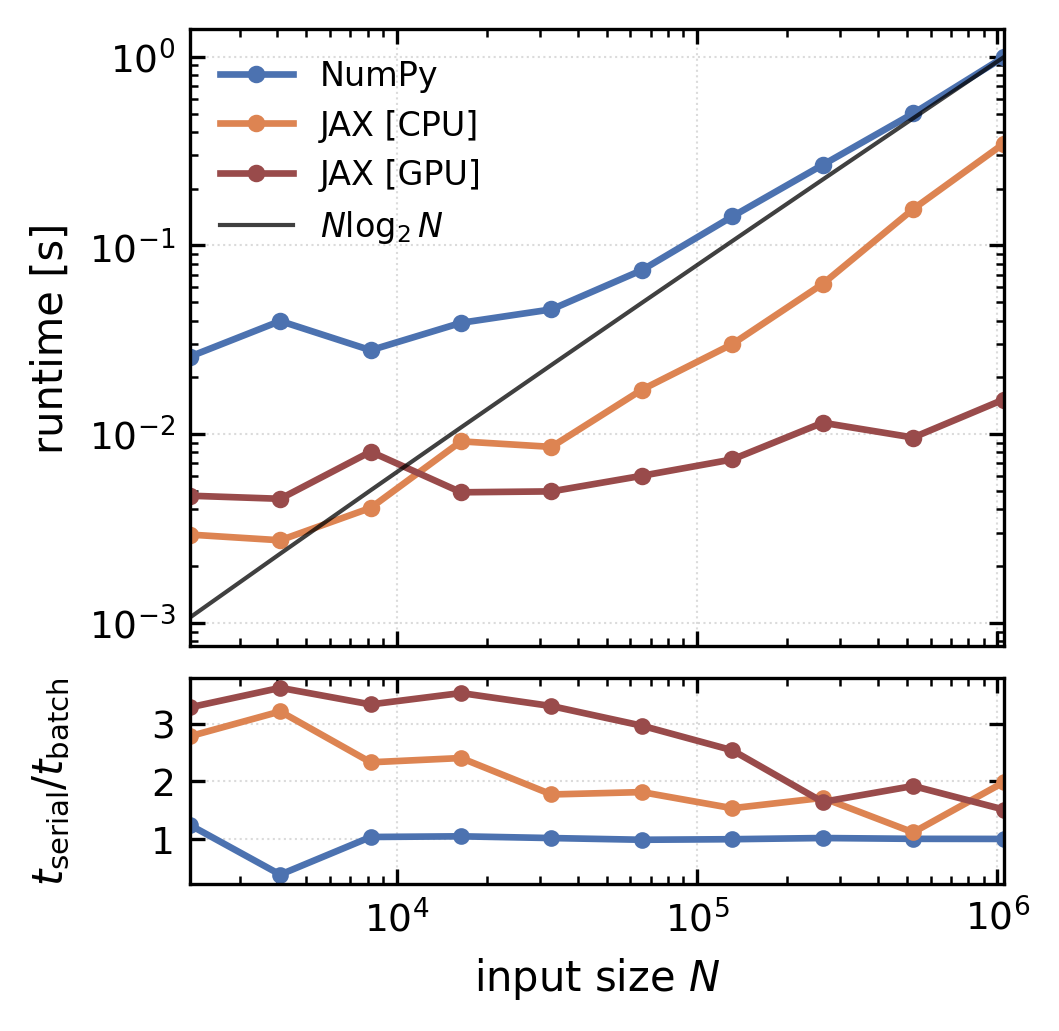
The raw numbers used for the plot are available in
benchmark_results.json.
Refreshing The Benchmark Snapshot
Regenerate the plot and JSON artifact manually from the repository root:
uv run python docs/examples/generate_benchmark_plot.py --backends numpy jax
If jax is not installed in the active environment, the script will warn and only emit the
available backends.
Notes
- The default benchmark range covers
N = 2048through33554432and uses 7 timed runs per point. - Refreshing the full default snapshot is now substantially more expensive than before.
- Each measurement uses one warmup call before timed runs.
- JAX timings are synchronized before the timer stops, so they include the actual device work.
- The timing panels show mean runtimes in milliseconds, with a shaded band for one standard deviation.
- The batched JAX panel compares one
3 x Ntransform against three independent single-series transforms. - Batched JAX execution is mainly a throughput optimization. It often wins for small and medium inputs because dispatch and kernel-launch overheads are amortized across the batch.
- At very large
N, FFT cost and memory traffic dominate. In that regime, the larger batched working set can increase memory-bandwidth pressure and temporary-allocation costs, so the batched call may show much smaller speedups or even become slower than running the channels serially. - The error panel shows the maximum absolute difference after
from_wdm_to_time(from_time_to_wdm(x)).
To generate benchmarks on Colab, you can run the following cell:
! pip install wdm_transform
! wdm_transform_benchmarking
FFT Reference Overlay
The runtime figure overlays a bare 1D FFT (dashed) on the WDM curves (solid) so the
WDM cost can be read relative to a single FFT. The WDM benchmark above does not
produce these FFT timings, so run the cell below to collect them. It uses the same
fixed-nt=1024 sweep (N = 2^11 … 2^24), 7 timed runs, one warmup, and device
synchronization.
Run it twice: once on a CPU runtime (records numpy + jax CPU rows) and once on
a GPU runtime (records jax GPU rows). Colab runtimes don't share a filesystem, so
download benchmark_fft_data.csv from each and concatenate the rows (keeping a single
header) into docs/_static/benchmark_fft_data.csv; then copy that file to
docs/manuscript/src/data/benchmark_fft_data.csv, which the manuscript figure reads.
# FFT runtime overlay for the figure's dashed reference curves.
# Self-contained: mirrors the WDM benchmark methodology (fixed nt=1024 sweep,
# 7 timed runs, one warmup, device sync). Run this cell BOTH on a CPU Colab
# runtime (gives numpy + jax[CPU] rows) and on a GPU runtime (gives jax[GPU]).
# Each run writes benchmark_fft_data.csv; since Colab runtimes do not share a
# filesystem, download the CSV from each runtime and concatenate the rows
# (keep one header) into docs/_static/benchmark_fft_data.csv, then copy it to
# docs/manuscript/src/data/benchmark_fft_data.csv.
import os, shutil, time
from pathlib import Path
import numpy as np

FIXED_NT = 1024
N_VALUES = [FIXED_NT * 2 ** p for p in range(1, 15)]  # N = 2^11 .. 2^24
BATCH, NUM_RUNS = 3, 7

DEVICE = "GPU" if shutil.which("nvidia-smi") else "CPU"
os.environ.setdefault("JAX_PLATFORMS", "cuda" if DEVICE == "GPU" else "cpu")


def _sync(v):
    if hasattr(v, "block_until_ready"):
        v.block_until_ready()


def _time(fn):
    _sync(fn())  # warmup (excluded)
    s = []
    for _ in range(NUM_RUNS):
        t0 = time.perf_counter()
        r = fn()
        _sync(r)
        s.append(time.perf_counter() - t0)
    return float(np.median(s)) * 1e3


def bench_numpy(n):
    rng = np.random.default_rng(42)
    x, xb = rng.standard_normal(n), rng.standard_normal((BATCH, n))
    return (
        _time(lambda: np.fft.fft(x)),
        _time(lambda: np.fft.fft(xb, axis=-1)),
        _time(lambda: [np.fft.fft(xb[i]) for i in range(BATCH)]),
    )


def bench_jax(n):
    import jax
    import jax.numpy as jnp
    rng = np.random.default_rng(42)
    x, xb = jnp.asarray(rng.standard_normal(n)), jnp.asarray(rng.standard_normal((BATCH, n)))
    fs, fb = jax.jit(jnp.fft.fft), jax.jit(lambda z: jnp.fft.fft(z, axis=-1))
    return (
        _time(lambda: fs(x)),
        _time(lambda: fb(xb)),
        _time(lambda: [fs(xb[i]) for i in range(BATCH)]),
    )


libraries = ["numpy", "jax"] if DEVICE == "CPU" else ["jax"]
out = Path("benchmark_fft_data.csv")
header = "device,library,N,scalar_ms,batch_ms,serial_ms,speedup"
rows = []
if out.exists():  # keep rows for other devices when run twice on one machine
    rows = [ln for ln in out.read_text().strip().splitlines()[1:]
            if not ln.startswith(f"{DEVICE},")]

print(f"Device: {DEVICE}")
for lib in libraries:
    print(f"\nLibrary: {lib}")
    bench = bench_numpy if lib == "numpy" else bench_jax
    for n in N_VALUES:
        sc, ba, se = bench(n)
        sp = se / ba if ba else float("nan")
        print(f"  N={n:>9}: scalar={sc:>9.3f} ms | batch={ba:>9.3f} ms | "
              f"serial={se:>9.3f} ms | speedup={sp:>5.2f}x")
        rows.append(f"{DEVICE},{lib},{n},{sc:.3f},{ba:.3f},{se:.3f},{sp:.2f}")

out.write_text(header + "\n" + "\n".join(rows) + "\n")
print(f"\nSaved/merged FFT rows into {out.resolve()}")
Device: CPU
JAX devices: [CpuDevice(id=0)]

========================================================================
Forward Kernel: from_freq_to_wdm
========================================================================

Backend: numpy
--------------------------------------------
  N=    2048: scalar=    4.458 ms | batch=   25.740 ms | serial 3x=   31.907 ms | speedup=  1.22x
  N=    4096: scalar=   16.104 ms | batch=   39.771 ms | serial 3x=   14.960 ms | speedup=  0.43x
  N=    8192: scalar=    9.085 ms | batch=   27.840 ms | serial 3x=   28.696 ms | speedup=  1.02x
  N=   16384: scalar=   13.432 ms | batch=   38.901 ms | serial 3x=   40.549 ms | speedup=  1.05x
  N=   32768: scalar=   26.191 ms | batch=   45.824 ms | serial 3x=   46.384 ms | speedup=  1.00x
  N=   65536: scalar=   24.392 ms | batch=   73.988 ms | serial 3x=   72.680 ms | speedup=  0.99x
  N=  131072: scalar=   47.017 ms | batch=  142.336 ms | serial 3x=  141.210 ms | speedup=  0.96x
  N=  262144: scalar=   85.764 ms | batch=  267.249 ms | serial 3x=  270.644 ms | speedup=  1.03x
  N=  524288: scalar=  191.644 ms | batch=  500.352 ms | serial 3x=  499.665 ms | speedup=  1.00x
  N= 1048576: scalar=  464.497 ms | batch=  993.021 ms | serial 3x=  990.045 ms | speedup=  1.01x

Backend: jax
--------------------------------------------
  N=    2048: scalar=    2.754 ms | batch=    2.937 ms | serial 3x=    8.173 ms | speedup=  2.80x
  N=    4096: scalar=    3.302 ms | batch=    2.740 ms | serial 3x=    8.809 ms | speedup=  3.21x
  N=    8192: scalar=    3.243 ms | batch=    4.068 ms | serial 3x=    9.479 ms | speedup=  2.29x
  N=   16384: scalar=    7.113 ms | batch=    9.157 ms | serial 3x=   22.017 ms | speedup=  2.44x
  N=   32768: scalar=    5.315 ms | batch=    8.562 ms | serial 3x=   15.159 ms | speedup=  1.79x
  N=   65536: scalar=    9.863 ms | batch=   17.201 ms | serial 3x=   31.163 ms | speedup=  1.78x
  N=  131072: scalar=   15.113 ms | batch=   30.003 ms | serial 3x=   45.941 ms | speedup=  1.54x
  N=  262144: scalar=   33.375 ms | batch=   62.571 ms | serial 3x=  107.104 ms | speedup=  1.68x
  N=  524288: scalar=   90.888 ms | batch=  155.826 ms | serial 3x=  173.105 ms | speedup=  1.14x
  N= 1048576: scalar=  145.134 ms | batch=  345.835 ms | serial 3x=  685.125 ms | speedup=  2.04x

========================================================================
Inverse Kernel: from_wdm_to_freq
========================================================================

Backend: numpy
--------------------------------------------
  N=    2048: scalar=    2.265 ms | batch=    6.681 ms | serial 3x=    6.892 ms | speedup=  1.03x
  N=    4096: scalar=    2.851 ms | batch=    8.285 ms | serial 3x=    8.552 ms | speedup=  1.03x
  N=    8192: scalar=    5.197 ms | batch=   15.473 ms | serial 3x=   16.920 ms | speedup=  1.09x
  N=   16384: scalar=    7.645 ms | batch=   22.558 ms | serial 3x=   23.186 ms | speedup=  1.01x
  N=   32768: scalar=   14.915 ms | batch=   43.517 ms | serial 3x=   43.631 ms | speedup=  1.00x
  N=   65536: scalar=   24.755 ms | batch=   72.503 ms | serial 3x=   72.463 ms | speedup=  1.01x
  N=  131072: scalar=   45.285 ms | batch=  135.758 ms | serial 3x=  138.545 ms | speedup=  1.01x
  N=  262144: scalar=   85.530 ms | batch=  363.908 ms | serial 3x=  269.843 ms | speedup=  0.71x
  N=  524288: scalar=  161.774 ms | batch=  490.935 ms | serial 3x=  500.774 ms | speedup=  1.03x
  N= 1048576: scalar=  338.566 ms | batch=  998.151 ms | serial 3x= 1002.523 ms | speedup=  1.00x

Backend: jax
--------------------------------------------
  N=    2048: scalar=    1.998 ms | batch=    2.338 ms | serial 3x=    7.135 ms | speedup=  3.08x
  N=    4096: scalar=    1.937 ms | batch=    2.731 ms | serial 3x=    7.391 ms | speedup=  2.67x
  N=    8192: scalar=    2.053 ms | batch=    7.509 ms | serial 3x=   14.874 ms | speedup=  2.00x
  N=   16384: scalar=    6.466 ms | batch=    9.911 ms | serial 3x=   11.593 ms | speedup=  1.15x
  N=   32768: scalar=    5.396 ms | batch=    8.347 ms | serial 3x=   15.166 ms | speedup=  1.80x
  N=   65536: scalar=    9.781 ms | batch=   17.492 ms | serial 3x=   30.227 ms | speedup=  1.73x
  N=  131072: scalar=   13.948 ms | batch=   33.352 ms | serial 3x=   46.744 ms | speedup=  1.40x
  N=  262144: scalar=   31.602 ms | batch=   66.548 ms | serial 3x=  103.055 ms | speedup=  1.56x
  N=  524288: scalar=   50.732 ms | batch=  163.410 ms | serial 3x=  274.656 ms | speedup=  1.70x
  N= 1048576: scalar=  131.664 ms | batch=  404.925 ms | serial 3x=  429.132 ms | speedup=  1.08x

========================================================================
SUMMARY
========================================================================

Forward Kernel: from_freq_to_wdm
------------------------------------------------------------------------
  numpy
    N=    2048 | scalar=    4.458 ms | batch=   25.740 ms | serial=   31.907 ms | speedup=  1.22x
    N=    4096 | scalar=   16.104 ms | batch=   39.771 ms | serial=   14.960 ms | speedup=  0.43x
    N=    8192 | scalar=    9.085 ms | batch=   27.840 ms | serial=   28.696 ms | speedup=  1.02x
    N=   16384 | scalar=   13.432 ms | batch=   38.901 ms | serial=   40.549 ms | speedup=  1.05x
    N=   32768 | scalar=   26.191 ms | batch=   45.824 ms | serial=   46.384 ms | speedup=  1.00x
    N=   65536 | scalar=   24.392 ms | batch=   73.988 ms | serial=   72.680 ms | speedup=  0.99x
    N=  131072 | scalar=   47.017 ms | batch=  142.336 ms | serial=  141.210 ms | speedup=  0.96x
    N=  262144 | scalar=   85.764 ms | batch=  267.249 ms | serial=  270.644 ms | speedup=  1.03x
    N=  524288 | scalar=  191.644 ms | batch=  500.352 ms | serial=  499.665 ms | speedup=  1.00x
    N= 1048576 | scalar=  464.497 ms | batch=  993.021 ms | serial=  990.045 ms | speedup=  1.01x
  jax
    N=    2048 | scalar=    2.754 ms | batch=    2.937 ms | serial=    8.173 ms | speedup=  2.80x
    N=    4096 | scalar=    3.302 ms | batch=    2.740 ms | serial=    8.809 ms | speedup=  3.21x
    N=    8192 | scalar=    3.243 ms | batch=    4.068 ms | serial=    9.479 ms | speedup=  2.29x
    N=   16384 | scalar=    7.113 ms | batch=    9.157 ms | serial=   22.017 ms | speedup=  2.44x
    N=   32768 | scalar=    5.315 ms | batch=    8.562 ms | serial=   15.159 ms | speedup=  1.79x
    N=   65536 | scalar=    9.863 ms | batch=   17.201 ms | serial=   31.163 ms | speedup=  1.78x
    N=  131072 | scalar=   15.113 ms | batch=   30.003 ms | serial=   45.941 ms | speedup=  1.54x
    N=  262144 | scalar=   33.375 ms | batch=   62.571 ms | serial=  107.104 ms | speedup=  1.68x
    N=  524288 | scalar=   90.888 ms | batch=  155.826 ms | serial=  173.105 ms | speedup=  1.14x
    N= 1048576 | scalar=  145.134 ms | batch=  345.835 ms | serial=  685.125 ms | speedup=  2.04x

Inverse Kernel: from_wdm_to_freq
------------------------------------------------------------------------
  numpy
    N=    2048 | scalar=    2.265 ms | batch=    6.681 ms | serial=    6.892 ms | speedup=  1.03x
    N=    4096 | scalar=    2.851 ms | batch=    8.285 ms | serial=    8.552 ms | speedup=  1.03x
    N=    8192 | scalar=    5.197 ms | batch=   15.473 ms | serial=   16.920 ms | speedup=  1.09x
    N=   16384 | scalar=    7.645 ms | batch=   22.558 ms | serial=   23.186 ms | speedup=  1.01x
    N=   32768 | scalar=   14.915 ms | batch=   43.517 ms | serial=   43.631 ms | speedup=  1.00x
    N=   65536 | scalar=   24.755 ms | batch=   72.503 ms | serial=   72.463 ms | speedup=  1.01x
    N=  131072 | scalar=   45.285 ms | batch=  135.758 ms | serial=  138.545 ms | speedup=  1.01x
    N=  262144 | scalar=   85.530 ms | batch=  363.908 ms | serial=  269.843 ms | speedup=  0.71x
    N=  524288 | scalar=  161.774 ms | batch=  490.935 ms | serial=  500.774 ms | speedup=  1.03x
    N= 1048576 | scalar=  338.566 ms | batch=  998.151 ms | serial= 1002.523 ms | speedup=  1.00x
  jax
    N=    2048 | scalar=    1.998 ms | batch=    2.338 ms | serial=    7.135 ms | speedup=  3.08x
    N=    4096 | scalar=    1.937 ms | batch=    2.731 ms | serial=    7.391 ms | speedup=  2.67x
    N=    8192 | scalar=    2.053 ms | batch=    7.509 ms | serial=   14.874 ms | speedup=  2.00x
    N=   16384 | scalar=    6.466 ms | batch=    9.911 ms | serial=   11.593 ms | speedup=  1.15x
    N=   32768 | scalar=    5.396 ms | batch=    8.347 ms | serial=   15.166 ms | speedup=  1.80x
    N=   65536 | scalar=    9.781 ms | batch=   17.492 ms | serial=   30.227 ms | speedup=  1.73x
    N=  131072 | scalar=   13.948 ms | batch=   33.352 ms | serial=   46.744 ms | speedup=  1.40x
    N=  262144 | scalar=   31.602 ms | batch=   66.548 ms | serial=  103.055 ms | speedup=  1.56x
    N=  524288 | scalar=   50.732 ms | batch=  163.410 ms | serial=  274.656 ms | speedup=  1.70x
    N= 1048576 | scalar=  131.664 ms | batch=  404.925 ms | serial=  429.132 ms | speedup=  1.08x

Saved JSON results to benchmark_artifacts/benchmark_results.json
Saved benchmark plot to benchmark_artifacts/benchmark_runtime.png
========================================================================
Forward Kernel: from_freq_to_wdm
========================================================================

Backend: numpy
--------------------------------------------
  N=    2048: scalar=    5.917 ms | batch=   15.511 ms | serial 3x=   12.738 ms | speedup=  0.82x
  N=    4096: scalar=    6.532 ms | batch=   14.389 ms | serial 3x=   17.107 ms | speedup=  1.19x
  N=    8192: scalar=    8.768 ms | batch=   25.069 ms | serial 3x=   29.540 ms | speedup=  1.17x
  N=   16384: scalar=   12.967 ms | batch=   34.083 ms | serial 3x=   36.064 ms | speedup=  1.07x
  N=   32768: scalar=   21.635 ms | batch=   40.109 ms | serial 3x=   41.646 ms | speedup=  1.01x
  N=   65536: scalar=   21.961 ms | batch=   68.833 ms | serial 3x=   69.782 ms | speedup=  1.03x
  N=  131072: scalar=   42.435 ms | batch=  130.507 ms | serial 3x=  130.032 ms | speedup=  0.99x
  N=  262144: scalar=   82.166 ms | batch=  237.491 ms | serial 3x=  339.709 ms | speedup=  1.41x
  N=  524288: scalar=  150.507 ms | batch=  463.294 ms | serial 3x=  470.540 ms | speedup=  0.98x
  N= 1048576: scalar=  412.646 ms | batch=  925.585 ms | serial 3x=  965.433 ms | speedup=  1.04x

Backend: jax
--------------------------------------------
  N=    2048: scalar=    4.861 ms | batch=    4.720 ms | serial 3x=   15.509 ms | speedup=  3.27x
  N=    4096: scalar=    5.217 ms | batch=    4.545 ms | serial 3x=   16.479 ms | speedup=  3.70x
  N=    8192: scalar=    8.210 ms | batch=    8.075 ms | serial 3x=   26.947 ms | speedup=  3.49x
  N=   16384: scalar=    5.865 ms | batch=    4.920 ms | serial 3x=   17.392 ms | speedup=  3.82x
  N=   32768: scalar=    5.350 ms | batch=    4.975 ms | serial 3x=   16.459 ms | speedup=  3.38x
  N=   65536: scalar=    6.034 ms | batch=    6.018 ms | serial 3x=   17.855 ms | speedup=  2.91x
  N=  131072: scalar=    6.545 ms | batch=    7.347 ms | serial 3x=   18.655 ms | speedup=  2.66x
  N=  262144: scalar=   10.357 ms | batch=   11.498 ms | serial 3x=   18.867 ms | speedup=  1.64x
  N=  524288: scalar=    8.594 ms | batch=    9.596 ms | serial 3x=   18.405 ms | speedup=  1.89x
  N= 1048576: scalar=   12.960 ms | batch=   15.255 ms | serial 3x=   23.018 ms | speedup=  1.50x

Backend: cupy
--------------------------------------------
  N=    2048: scalar=   32.521 ms | batch=  108.987 ms | serial 3x=   76.269 ms | speedup=  0.68x
  N=    4096: scalar=   23.944 ms | batch=   75.379 ms | serial 3x=   69.862 ms | speedup=  0.93x
  N=    8192: scalar=   49.723 ms | batch=  141.127 ms | serial 3x=  143.091 ms | speedup=  1.00x
  N=   16384: scalar=   47.792 ms | batch=  139.898 ms | serial 3x=  147.570 ms | speedup=  1.05x
  N=   32768: scalar=   91.693 ms | batch=  392.255 ms | serial 3x=  281.871 ms | speedup=  0.77x
  N=   65536: scalar=   95.341 ms | batch=  289.147 ms | serial 3x=  282.998 ms | speedup=  0.98x
  N=  131072: scalar=  192.553 ms | batch=  584.867 ms | serial 3x=  574.453 ms | speedup=  0.96x
  N=  262144: scalar=  198.532 ms | batch=  580.031 ms | serial 3x=  572.687 ms | speedup=  0.98x
  N=  524288: scalar=  544.619 ms | batch= 1122.384 ms | serial 3x= 1110.978 ms | speedup=  0.99x
  N= 1048576: scalar=  528.699 ms | batch= 1109.168 ms | serial 3x= 1130.090 ms | speedup=  1.02x

========================================================================
Inverse Kernel: from_wdm_to_freq
========================================================================

Backend: numpy
--------------------------------------------
  N=    2048: scalar=    2.075 ms | batch=    6.099 ms | serial 3x=    6.389 ms | speedup=  1.04x
  N=    4096: scalar=    2.626 ms | batch=    7.735 ms | serial 3x=    8.026 ms | speedup=  1.04x
  N=    8192: scalar=    5.220 ms | batch=   14.510 ms | serial 3x=   14.958 ms | speedup=  1.04x
  N=   16384: scalar=    6.903 ms | batch=   21.511 ms | serial 3x=   22.217 ms | speedup=  1.00x
  N=   32768: scalar=   13.171 ms | batch=   38.782 ms | serial 3x=   40.792 ms | speedup=  1.04x
  N=   65536: scalar=   21.457 ms | batch=   62.698 ms | serial 3x=   98.653 ms | speedup=  1.57x
  N=  131072: scalar=   61.727 ms | batch=  186.845 ms | serial 3x=  119.999 ms | speedup=  0.64x
  N=  262144: scalar=   74.355 ms | batch=  230.790 ms | serial 3x=  235.094 ms | speedup=  1.02x
  N=  524288: scalar=  146.481 ms | batch=  459.847 ms | serial 3x=  449.249 ms | speedup=  0.95x
  N= 1048576: scalar=  295.719 ms | batch=  925.629 ms | serial 3x=  887.321 ms | speedup=  0.96x

Backend: jax
--------------------------------------------
  N=    2048: scalar=    6.230 ms | batch=    7.559 ms | serial 3x=   25.074 ms | speedup=  3.03x
  N=    4096: scalar=    5.845 ms | batch=    4.758 ms | serial 3x=   15.911 ms | speedup=  3.55x
  N=    8192: scalar=    4.453 ms | batch=    4.429 ms | serial 3x=   15.789 ms | speedup=  3.68x
  N=   16384: scalar=    3.970 ms | batch=    4.450 ms | serial 3x=   16.372 ms | speedup=  3.69x
  N=   32768: scalar=    4.871 ms | batch=    4.818 ms | serial 3x=   17.441 ms | speedup=  3.52x
  N=   65536: scalar=    4.501 ms | batch=    5.027 ms | serial 3x=   16.290 ms | speedup=  3.23x
  N=  131072: scalar=    4.756 ms | batch=    4.748 ms | serial 3x=   15.790 ms | speedup=  3.33x
  N=  262144: scalar=    4.624 ms | batch=    8.410 ms | serial 3x=   23.513 ms | speedup=  2.76x
  N=  524288: scalar=    6.725 ms | batch=    9.465 ms | serial 3x=   15.504 ms | speedup=  1.64x
  N= 1048576: scalar=   10.469 ms | batch=   20.320 ms | serial 3x=   21.111 ms | speedup=  1.20x

Backend: cupy
--------------------------------------------
  N=    2048: scalar=   21.234 ms | batch=   60.175 ms | serial 3x=   62.125 ms | speedup=  1.01x
  N=    4096: scalar=   21.241 ms | batch=   61.103 ms | serial 3x=   63.151 ms | speedup=  1.01x
  N=    8192: scalar=   42.611 ms | batch=  120.312 ms | serial 3x=  125.988 ms | speedup=  1.05x
  N=   16384: scalar=   40.946 ms | batch=  168.397 ms | serial 3x=  174.575 ms | speedup=  1.12x
  N=   32768: scalar=   79.314 ms | batch=  238.617 ms | serial 3x=  242.138 ms | speedup=  1.03x
  N=   65536: scalar=   80.039 ms | batch=  236.975 ms | serial 3x=  259.056 ms | speedup=  1.03x
  N=  131072: scalar=  161.993 ms | batch=  475.923 ms | serial 3x=  483.335 ms | speedup=  1.00x
  N=  262144: scalar=  168.951 ms | batch=  487.539 ms | serial 3x=  486.211 ms | speedup=  1.00x
  N=  524288: scalar=  331.027 ms | batch=  948.665 ms | serial 3x=  960.568 ms | speedup=  1.01x
  N= 1048576: scalar=  315.858 ms | batch=  959.198 ms | serial 3x=  958.334 ms | speedup=  0.99x

========================================================================
SUMMARY
========================================================================

Forward Kernel: from_freq_to_wdm
------------------------------------------------------------------------
  numpy
    N=    2048 | scalar=    5.917 ms | batch=   15.511 ms | serial=   12.738 ms | speedup=  0.82x
    N=    4096 | scalar=    6.532 ms | batch=   14.389 ms | serial=   17.107 ms | speedup=  1.19x
    N=    8192 | scalar=    8.768 ms | batch=   25.069 ms | serial=   29.540 ms | speedup=  1.17x
    N=   16384 | scalar=   12.967 ms | batch=   34.083 ms | serial=   36.064 ms | speedup=  1.07x
    N=   32768 | scalar=   21.635 ms | batch=   40.109 ms | serial=   41.646 ms | speedup=  1.01x
    N=   65536 | scalar=   21.961 ms | batch=   68.833 ms | serial=   69.782 ms | speedup=  1.03x
    N=  131072 | scalar=   42.435 ms | batch=  130.507 ms | serial=  130.032 ms | speedup=  0.99x
    N=  262144 | scalar=   82.166 ms | batch=  237.491 ms | serial=  339.709 ms | speedup=  1.41x
    N=  524288 | scalar=  150.507 ms | batch=  463.294 ms | serial=  470.540 ms | speedup=  0.98x
    N= 1048576 | scalar=  412.646 ms | batch=  925.585 ms | serial=  965.433 ms | speedup=  1.04x
  jax
    N=    2048 | scalar=    4.861 ms | batch=    4.720 ms | serial=   15.509 ms | speedup=  3.27x
    N=    4096 | scalar=    5.217 ms | batch=    4.545 ms | serial=   16.479 ms | speedup=  3.70x
    N=    8192 | scalar=    8.210 ms | batch=    8.075 ms | serial=   26.947 ms | speedup=  3.49x
    N=   16384 | scalar=    5.865 ms | batch=    4.920 ms | serial=   17.392 ms | speedup=  3.82x
    N=   32768 | scalar=    5.350 ms | batch=    4.975 ms | serial=   16.459 ms | speedup=  3.38x
    N=   65536 | scalar=    6.034 ms | batch=    6.018 ms | serial=   17.855 ms | speedup=  2.91x
    N=  131072 | scalar=    6.545 ms | batch=    7.347 ms | serial=   18.655 ms | speedup=  2.66x
    N=  262144 | scalar=   10.357 ms | batch=   11.498 ms | serial=   18.867 ms | speedup=  1.64x
    N=  524288 | scalar=    8.594 ms | batch=    9.596 ms | serial=   18.405 ms | speedup=  1.89x
    N= 1048576 | scalar=   12.960 ms | batch=   15.255 ms | serial=   23.018 ms | speedup=  1.50x
  cupy
    N=    2048 | scalar=   32.521 ms | batch=  108.987 ms | serial=   76.269 ms | speedup=  0.68x
    N=    4096 | scalar=   23.944 ms | batch=   75.379 ms | serial=   69.862 ms | speedup=  0.93x
    N=    8192 | scalar=   49.723 ms | batch=  141.127 ms | serial=  143.091 ms | speedup=  1.00x
    N=   16384 | scalar=   47.792 ms | batch=  139.898 ms | serial=  147.570 ms | speedup=  1.05x
    N=   32768 | scalar=   91.693 ms | batch=  392.255 ms | serial=  281.871 ms | speedup=  0.77x
    N=   65536 | scalar=   95.341 ms | batch=  289.147 ms | serial=  282.998 ms | speedup=  0.98x
    N=  131072 | scalar=  192.553 ms | batch=  584.867 ms | serial=  574.453 ms | speedup=  0.96x
    N=  262144 | scalar=  198.532 ms | batch=  580.031 ms | serial=  572.687 ms | speedup=  0.98x
    N=  524288 | scalar=  544.619 ms | batch= 1122.384 ms | serial= 1110.978 ms | speedup=  0.99x
    N= 1048576 | scalar=  528.699 ms | batch= 1109.168 ms | serial= 1130.090 ms | speedup=  1.02x

Inverse Kernel: from_wdm_to_freq
------------------------------------------------------------------------
  numpy
    N=    2048 | scalar=    2.075 ms | batch=    6.099 ms | serial=    6.389 ms | speedup=  1.04x
    N=    4096 | scalar=    2.626 ms | batch=    7.735 ms | serial=    8.026 ms | speedup=  1.04x
    N=    8192 | scalar=    5.220 ms | batch=   14.510 ms | serial=   14.958 ms | speedup=  1.04x
    N=   16384 | scalar=    6.903 ms | batch=   21.511 ms | serial=   22.217 ms | speedup=  1.00x
    N=   32768 | scalar=   13.171 ms | batch=   38.782 ms | serial=   40.792 ms | speedup=  1.04x
    N=   65536 | scalar=   21.457 ms | batch=   62.698 ms | serial=   98.653 ms | speedup=  1.57x
    N=  131072 | scalar=   61.727 ms | batch=  186.845 ms | serial=  119.999 ms | speedup=  0.64x
    N=  262144 | scalar=   74.355 ms | batch=  230.790 ms | serial=  235.094 ms | speedup=  1.02x
    N=  524288 | scalar=  146.481 ms | batch=  459.847 ms | serial=  449.249 ms | speedup=  0.95x
    N= 1048576 | scalar=  295.719 ms | batch=  925.629 ms | serial=  887.321 ms | speedup=  0.96x
  jax
    N=    2048 | scalar=    6.230 ms | batch=    7.559 ms | serial=   25.074 ms | speedup=  3.03x
    N=    4096 | scalar=    5.845 ms | batch=    4.758 ms | serial=   15.911 ms | speedup=  3.55x
    N=    8192 | scalar=    4.453 ms | batch=    4.429 ms | serial=   15.789 ms | speedup=  3.68x
    N=   16384 | scalar=    3.970 ms | batch=    4.450 ms | serial=   16.372 ms | speedup=  3.69x
    N=   32768 | scalar=    4.871 ms | batch=    4.818 ms | serial=   17.441 ms | speedup=  3.52x
    N=   65536 | scalar=    4.501 ms | batch=    5.027 ms | serial=   16.290 ms | speedup=  3.23x
    N=  131072 | scalar=    4.756 ms | batch=    4.748 ms | serial=   15.790 ms | speedup=  3.33x
    N=  262144 | scalar=    4.624 ms | batch=    8.410 ms | serial=   23.513 ms | speedup=  2.76x
    N=  524288 | scalar=    6.725 ms | batch=    9.465 ms | serial=   15.504 ms | speedup=  1.64x
    N= 1048576 | scalar=   10.469 ms | batch=   20.320 ms | serial=   21.111 ms | speedup=  1.20x
  cupy
    N=    2048 | scalar=   21.234 ms | batch=   60.175 ms | serial=   62.125 ms | speedup=  1.01x
    N=    4096 | scalar=   21.241 ms | batch=   61.103 ms | serial=   63.151 ms | speedup=  1.01x
    N=    8192 | scalar=   42.611 ms | batch=  120.312 ms | serial=  125.988 ms | speedup=  1.05x
    N=   16384 | scalar=   40.946 ms | batch=  168.397 ms | serial=  174.575 ms | speedup=  1.12x
    N=   32768 | scalar=   79.314 ms | batch=  238.617 ms | serial=  242.138 ms | speedup=  1.03x
    N=   65536 | scalar=   80.039 ms | batch=  236.975 ms | serial=  259.056 ms | speedup=  1.03x
    N=  131072 | scalar=  161.993 ms | batch=  475.923 ms | serial=  483.335 ms | speedup=  1.00x
    N=  262144 | scalar=  168.951 ms | batch=  487.539 ms | serial=  486.211 ms | speedup=  1.00x
    N=  524288 | scalar=  331.027 ms | batch=  948.665 ms | serial=  960.568 ms | speedup=  1.01x
    N= 1048576 | scalar=  315.858 ms | batch=  959.198 ms | serial=  958.334 ms | speedup=  0.99x

Saved JSON results to benchmark_artifacts/benchmark_results.json
Saved benchmark plot to benchmark_artifacts/benchmark_runtime.png
import numpy as np
import pandas as pd
import matplotlib.pyplot as plt

# -----------------------
# Load data
# -----------------------
data = pd.read_csv(
    "https://raw.githubusercontent.com/pywavelet/wdm_transform/refs/heads/main/docs/_static/benchmark_data.csv"
)

data["label"] = (
    data["library"].str.lower().map({"numpy": "NumPy", "jax": "JAX"})
    + " "
    + data["device"]
)

data["batch_s"] = data["batch_ms"] / 1000.0
data["speedup_batch_vs_serial"] = data["serial_ms"] / data["batch_ms"]

def make_label(row):
    if row["library"] == "numpy":
        return "NumPy"
    elif row["library"] == "jax" and row["device"] == "CPU":
        return "JAX [CPU]"
    elif row["library"] == "jax" and row["device"] == "GPU":
        return "JAX [GPU]"
    else:
        return f"{row['library']} [{row['device']}]"

data["label"] = data.apply(make_label, axis=1)

order = ["NumPy", "JAX [CPU]", "JAX [GPU]"]

# -----------------------
# Paper-style plotting
# -----------------------
plt.rcParams.update({
    "font.size": 9,
    "axes.labelsize": 10,
    "axes.titlesize": 10,
    "legend.fontsize": 8,
    "xtick.labelsize": 9,
    "ytick.labelsize": 9,
    "lines.linewidth": 1.4,
    "axes.linewidth": 0.8,
    "xtick.direction": "in",
    "ytick.direction": "in",
    "xtick.top": True,
    "ytick.right": True,
    "savefig.dpi": 300,
})
colors = {
    "NumPy": "#4C72B0",
    "JAX [CPU]": "#DD8452",
    "JAX [GPU]": "#994B4B",
}

fig, (ax, ax_sp) = plt.subplots(
    2,
    1,
    figsize=(3.5, 3.7),
    sharex=True,
    gridspec_kw={"height_ratios": [3.0, 1.0], "hspace": 0.08},
)

# -----------------------
# Top panel: batched runtime
# -----------------------
for label in order:
    df = data[data["label"] == label].sort_values("N")
    if df.empty:
        continue

    ax.loglog(
        df["N"],
        df["batch_s"],
        marker="o",
        ms=3.2,
        lw=1.6,
        label=label,
        color=colors.get(label, "black"),
    )

# N log N reference, anchored to final NumPy CPU point
ref_df = data[data["label"] == "NumPy"].sort_values("N")
N_ref = ref_df["N"].to_numpy()
t_ref = ref_df["batch_s"].to_numpy()
ref = N_ref * np.log2(N_ref)
ref = ref / ref[-1] * t_ref[-1]

ax.loglog(
    N_ref,
    ref,
    color='black',
    ls="-",
    lw=1.0,
    alpha=0.75,
    label=r"$N\log_2 N$",
)

ax.set_ylabel(r"runtime [s]")
ax.grid(True, which="major", ls=":", lw=0.5, alpha=0.45)
ax.grid(False, which="minor")
ax.legend(frameon=False, loc="upper left", handlelength=2.2)

# -----------------------
# Bottom panel: batching speedup
# -----------------------
for label in order:
    df = data[data["label"] == label].sort_values("N")
    if df.empty:
        continue

    ax_sp.semilogx(
        df["N"],
        df["speedup_batch_vs_serial"],
        marker="o",
        ms=3.0,
        lw=1.6,
        color=colors.get(label, "black"),
    )

# ax_sp.axhline(1.0, ls="--", lw=0.9, alpha=0.7)

ax_sp.set_xlabel(r"input size $N$")
ax_sp.set_ylabel(r"$t_{\rm serial}/t_{\rm batch}$")
ax_sp.grid(True, which="major", ls=":", lw=0.5, alpha=0.45)
ax_sp.grid(False, which="minor")
ax_sp.set_xlim(N_ref.min(), N_ref.max())
fig.align_ylabels()

fig.savefig("_static/benchmark_scaling.png", dpi=300, bbox_inches="tight")

plt.close(fig)